Platform
Deployments, infrastructure, or Kubernetes operations feel fragile or hard to change.
Trace the path from change to production. Improve the highest-risk automation, infrastructure, deployment, or rollback path that evidence supports.
Run & Scale · Platform, observability, recovery
Find the reliability constraint that matters to the business, then fix or prove the highest-risk path.
One entry review. One focused sprint. Three connected tracks—not a technology shopping list.
Discuss your platformFit
Tracks
Deployments, infrastructure, or Kubernetes operations feel fragile or hard to change.
Trace the path from change to production. Improve the highest-risk automation, infrastructure, deployment, or rollback path that evidence supports.
Dashboards exist, but they do not help someone decide what is broken or what to do next.
Connect workload signals to collection, storage, alerts, and operational decisions. Use Prometheus-compatible tooling, VictoriaMetrics or Mimir, and Grafana where they fit.
Backups exist, but the recovery path or recovery objective has not been demonstrated.
Review backup assumptions, restore procedures, point-in-time recovery, observability, and runbooks. A restore is tested only when the customer environment and access permit it.
Engagement
Entry review
For production systems where database, cloud infrastructure, observability or reliability is creating operational risk. I diagnose the system and leave you with concrete priorities — then I can stay to implement them if useful.
from €1,500 · focused engagement
A scoped assessment, not an open-ended managed SRE service or staff-augmentation contract.
Follow-on
A fixed-scope intervention on the highest-value agreed platform, observability, or recovery gap. The outcome, access, and definition of done are agreed before work starts.
A sprint is not ongoing managed SRE or staff augmentation. Another sprint needs a separate outcome.
Proof
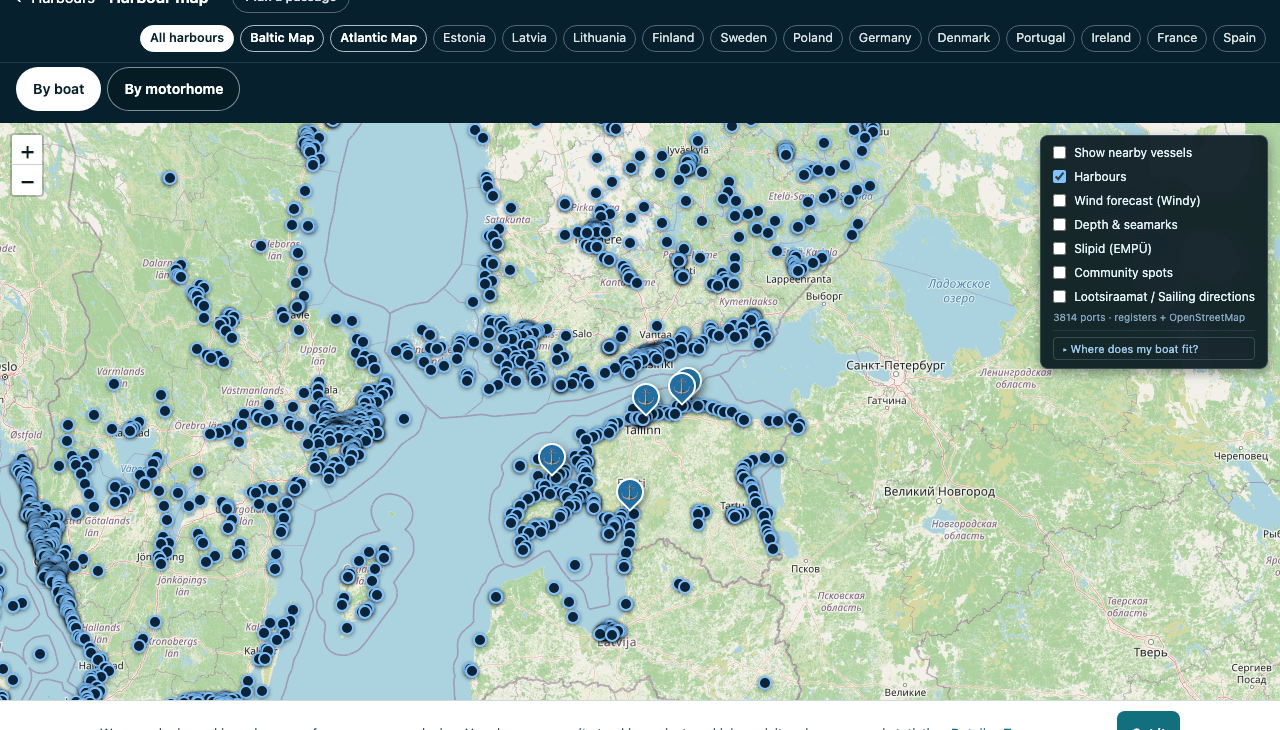
Mervare’s public system links a directory, bookings, payment integration, data pipelines, and an instrument bridge. The case study labels what is a live pilot, built, or not yet live.
Inspect the Mervare caseThe existing SRE / Database Reliability Review is priced from €1,500; sprint scopes are agreed separately.